Myco Brain
About
Self-hosted memory and knowledge-graph MCP server for AI agents. TypeScript on Postgres 16 + pgvector, 11 brain_* tools. Runs keyless: full-text and semantic search, ingestion, content-hash dedup, provenance via brain_why, and the knowledge graph all work with no API keys via local Ollama. Apache-2.0.
Explore
- Source-traceable: every fact links to its document (brain_why)
- Trust that compounds: corroboration raises confidence, contradiction supersedes (audited)
- Keyless & local-first: full-text + semantic search and knowledge graph run with zero hosted dependencies
- Dynamic schema: new entity/relationship types are proposed and promoted per workspace
- One isolated workspace per client, enforced by Postgres row-level security
- 11 MCP tools; works with multiple agent clients and a read-only HTTP REST API

Setting up with Highlight
This MCP is not yet compatible with Highlight’s one-click setup. However, you can still use it with Highlight by following these steps:
- Download and install Highlight from highlightai.com/download
- Navigate to the plugins tab and select "Add Custom Plugin"
-
Configure the plugin with the settings below
Plugin Name
Myco BrainCommand (node, npx, python, etc.)Please refer to the README for specific instructions on how to obtain API keys or other required environment variables.
- Enable "Start Automatically" if you want the plugin to start when Highlight launches





From the repository
npx -y -p @mycobrain/mcp-server mycobrain-ingest github:your-org/your-repo
npx -y -p @mycobrain/mcp-server mycobrain-onboard
ollama pull llama3.2:3b
The Docker quickstart needs none of these — it ships with seeded local
credentials and BM25 search works immediately. This is the reference for your
own deployment. Full annotated list with tuning thresholds:
.env.example. Not sure what's active? Run mycobrain-doctor.
Required
| Variable | Default | What it does |
|---|---|---|
| DATABASE_URL | — | Postgres connection string. The only hard requirement. |
| BRAIN_API_KEY | seeded | brain_<workspace>_<agent>_<secret> key; the quickstart ships a localdev key. |
| BRAIN_WORKSPACE_ID | from key | Derived from BRAIN_API_KEY; set explicitly only for service-role auth. |
Semantic search (optional — without it, BM25 full-text still works)
| Variable | Default | What it does |
|---|---|---|
| BRAIN_EMBED_PROVIDER | auto | ollama or openai; auto-selects by which credential is set. |
| BRAIN_OLLAMA_EMBED_MODEL | nomic-embed-text | Local embedding model (no key, nothing leaves your machine). |
| BRAIN_OPENAI_API_KEY | — | Use OpenAI embeddings instead of local. |
Knowledge graph (optional)
| Variable | Default | What it does |
|---|---|---|
| BRAIN_OLLAMA_BASE_URL | — | Local extraction/embeddings endpoint (e.g. http://localhost:11434). |
| BRAIN_OLLAMA_MODEL | llama3.2:3b | Local extraction model. |
| BRAIN_ANTHROPIC_API_KEY | — | Most accurate graph; used automatically if set. |
| BRAIN_EXTRACTION_PROVIDER | auto | Force ollama or anthropic. |
Trust dial (governance)
| Variable | Default | What it does |
|---|---|---|
| BRAIN_REQUIRE_HUMAN_REVIEW | 0 | Strict curation — nothing the LLM proposes enters the graph without a human decision. |
| BRAIN_SCHEMA_AUTO_PROMOTE | 0 | Let corroborated new types promote themselves, audited and workspace-scoped. |
Serving
| Variable | Default | What it does |
|---|---|---|
| BRAIN_REST_HOST | 127.0.0.1 | Bind host for mycobrain-rest. Use 0.0.0.0 only behind your own TLS/proxy. |
| BRAIN_REST_PORT | 8787 | Read-only REST port. |
| BRAIN_HEALTH_PORT | 8080 | Health-check port. |
Identity & security
| Variable | Default | What it does |
|---|---|---|
| BRAIN_REQUIRE_API_KEY_SECRET | 0 | Require a registered <secret> for every agent key before auth succeeds. |
| BRAIN_TRUST_REQUEST_IDENTITY | 0 | Stdio, multi-tenant gateways only. Off: identity comes solely from env, so a caller-supplied workspace_id/api_key is ignored (prompt-injection-resistant). Set 1 only behind a gateway that authenticates each request. Details ↑ |
| BRAIN_AGENT_ID | from key | Agent identity for service-role auth; derived from BRAIN_API_KEY otherwise. |
| BRAIN_SERVICE_ROLE_KEY | — | Supabase service-role JWT for trusted service callers (alternative to a brain_ key). |
> Tuning thresholds (BRAIN_SCHEMA_PROMOTE_MIN_SEEN, BRAIN_EXTRACTION_LEASE_MS, BRAIN_FUNCTIONAL_PREDICATES, …) live in .env.example.
brain_context_pack
`brain_search`
brain_why
`brain_neighbors`
brain_ingest
`brain_propose_fact`
brain_annotate
`brain_save_memory`
brain_recall_memory
`brain_get_related`
brain_stats
Full inputs, outputs, and examples for each tool: **[docs/api-reference.md](./docs/api-reference.md)**.
Myco Brain exposes 11 MCP tools:
- brain_context_pack
- brain_search
- brain_why
- brain_neighbors
- brain_ingest
- brain_propose_fact
- brain_annotate
- brain_save_memory
- brain_recall_memory
- brain_get_related
- brain_stats
Full inputs, outputs, and examples for each tool: docs/api-reference.md.
Claude Desktop / Cursor
Paste into your MCP client config file to install this server.
{
    "mcpServers": {
        "myco brain": {
            "myco-brain": {
                "command": "npx",
                "args": [
                    "-y",
                    "@mycobrain/mcp-server"
                ],
                "env": {
                    "DATABASE_URL": "postgresql://brain:brain@localhost:5432/brain",
                    "BRAIN_WORKSPACE_ID": "00000000-0000-0000-0000-000000000001",
                    "BRAIN_API_KEY": "brain_00000000-0000-0000-0000-000000000001_00000000-0000-0000-0000-0000000000a1_localdev"
                }
            }
        }
    }
}McpServers
{
    "myco-brain": {
        "command": "npx",
        "args": [
            "-y",
            "@mycobrain/mcp-server"
        ],
        "env": {
            "DATABASE_URL": "postgresql://brain:brain@localhost:5432/brain",
            "BRAIN_WORKSPACE_ID": "00000000-0000-0000-0000-000000000001",
            "BRAIN_API_KEY": "brain_00000000-0000-0000-0000-000000000001_00000000-0000-0000-0000-0000000000a1_localdev"
        }
    }
}
<p align="center">
<picture>
<source media="(prefers-color-scheme: dark)" srcset="./docs/assets/myco-logo-dark.png">
</picture>
</p>
Persistent, source-traceable memory for AI agents — self-hosted on your own Postgres, with no API keys required to run.


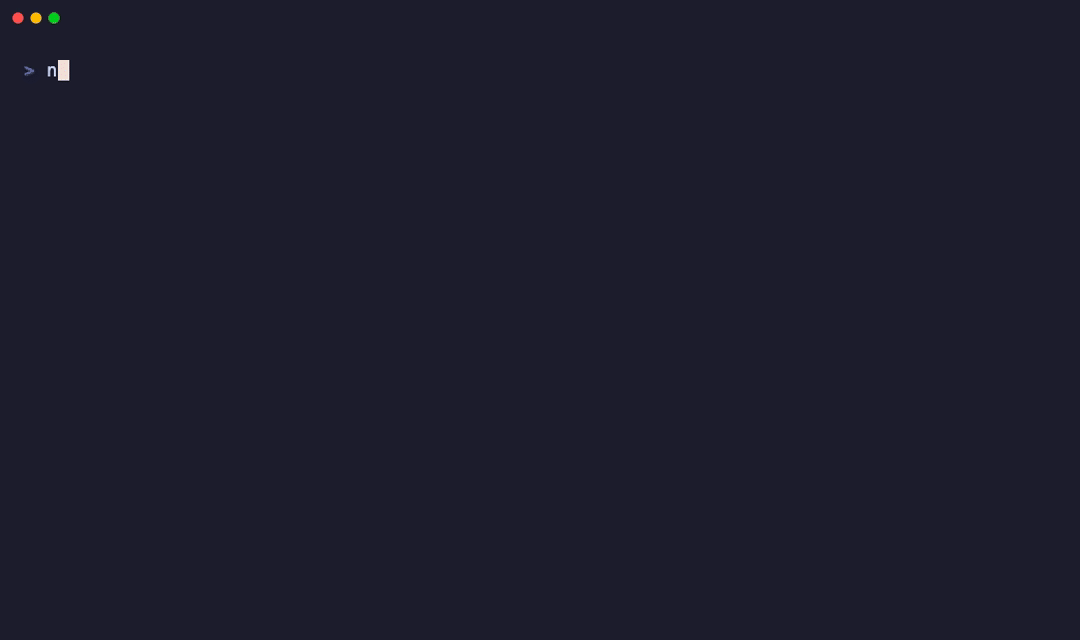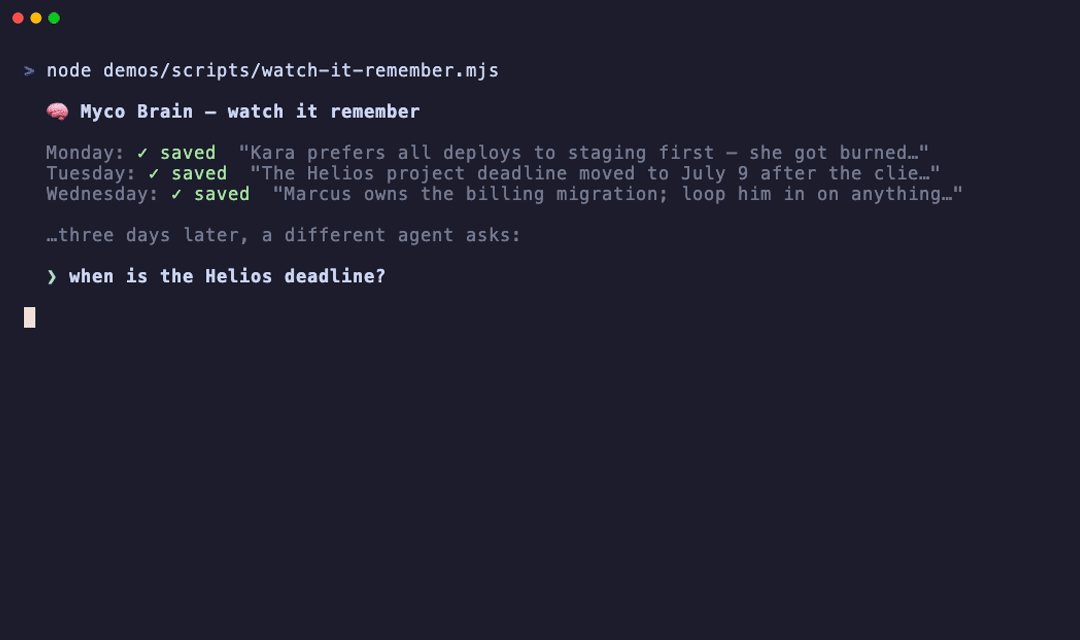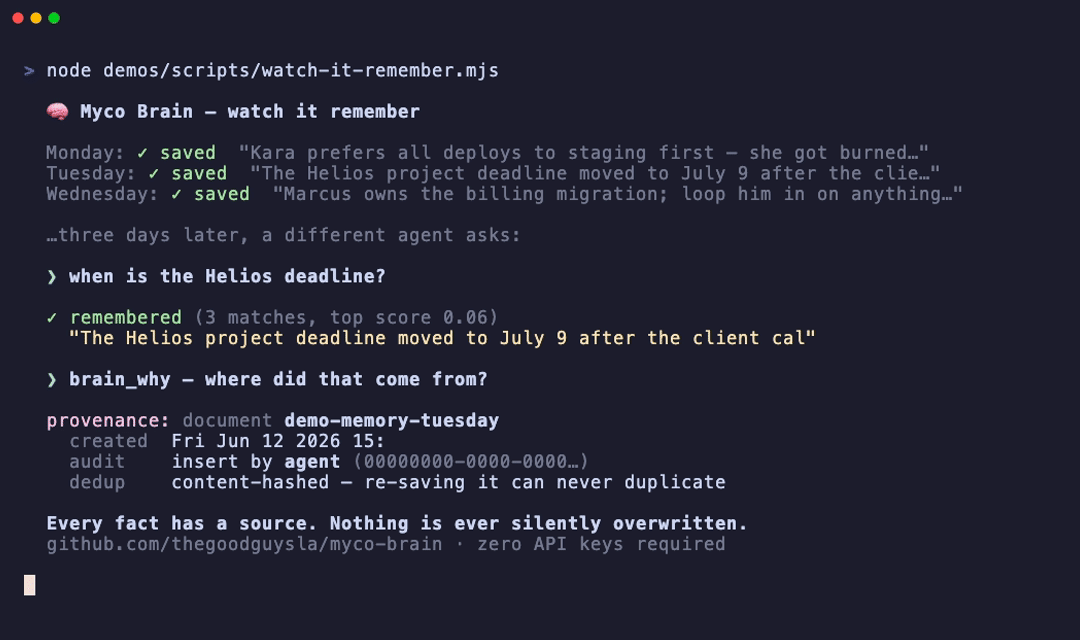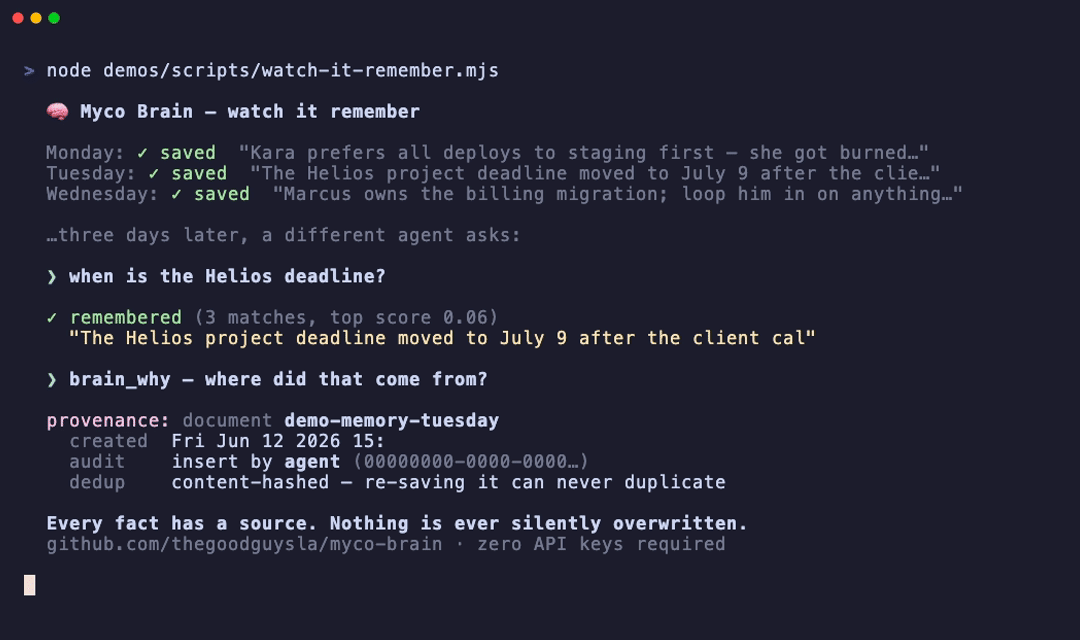
- Source-traceable. Every fact traces to the document it came from (brain_why) — no trust-me summaries.
- Trust that compounds. Independent corroboration _raises_ a fact's confidence; a contradiction _supersedes_ it — kept and audited, never silently overwritten.
- Keyless & local-first. Full-text + semantic search and the knowledge graph all run with zero hosted dependency — add an Anthropic key only for the most accurate graph.
- Yours. Apache-2.0, plain Postgres tables, 11 MCP tools. Works with Claude, Cursor, Windsurf, Continue, Zed.
Who it's for: dev teams running agents that need one shared memory · agencies needing hard per-client isolation · anyone who wants their assistant to remember across sessions — import your ChatGPT / Claude history and your AI knows you on day one.
_Built solo by a growth marketer — not a career engineer — directing AI coding agents over ~3 months. How it was built ↓_
The usual fix for agent amnesia — letting an LLM maintain its own memory —
fills it with duplicates, hallucinated summaries, and confident answers nobody
can trace. Myco Brain is built on the opposite contract:
> The LLM proposes. Deterministic rules decide what becomes a fact. You set
> the bar — from corroboration-gated auto-promotion (the default) to strict
> human review of every fact (BRAIN_REQUIRE_HUMAN_REVIEW=1).
Claude, Cursor, Windsurf, Continue, Zed, and custom agents all share one memory
backed by your own Postgres.
⭐ If the trust model resonates, a star helps others find it.
# 1. Boot the stack (Postgres + MCP server + extraction worker)
git clone https://github.com/thegoodguysla/myco-brain.git && cd myco-brain
docker compose up -d
2. Give your agent a memory — point it at any repo or folder
   (no env needed: it finds the quickstart stack on localhost)
npx -y -p @mycobrain/mcp-server mycobrain-ingest github:your-org/your-repo
3. Connect your client (one-liner below), then ask across sessions:
   "what did we decide about auth, and where is that documented?"
   → answered from your docs, with the source cited.
> [!TIP]
> Zero API keys, all the way down. Full-text search, semantic search (local
> embeddings), and the knowledge graph (local extraction) all run with no hosted
> dependency. Add an Anthropic key only if you want the most accurate graph.
MCP-native by design — your agent knows _when_ to use memory, not just _how_.
Most MCP servers expose tools and hope the model calls them. Myco ships a usage
contract over MCP's instructions channel: the moment it connects, your agent
knows to pull context before a task, save durable decisions, and cite sources
with brain_why — no per-project prompting. Tune the policy in one copy-paste
block: Teach your agent to use it well.
Quick links:
10-minute quickstart ·
Teach your agent to use it well ·
The trust engine ·
Benchmark — run it yourself ·
Run every proof ·
Who it's for ·
Environment variables ·
Architecture ·
Roadmap ·
Cloud waitlist
Memory that gets more trustworthy (compounding confidence)
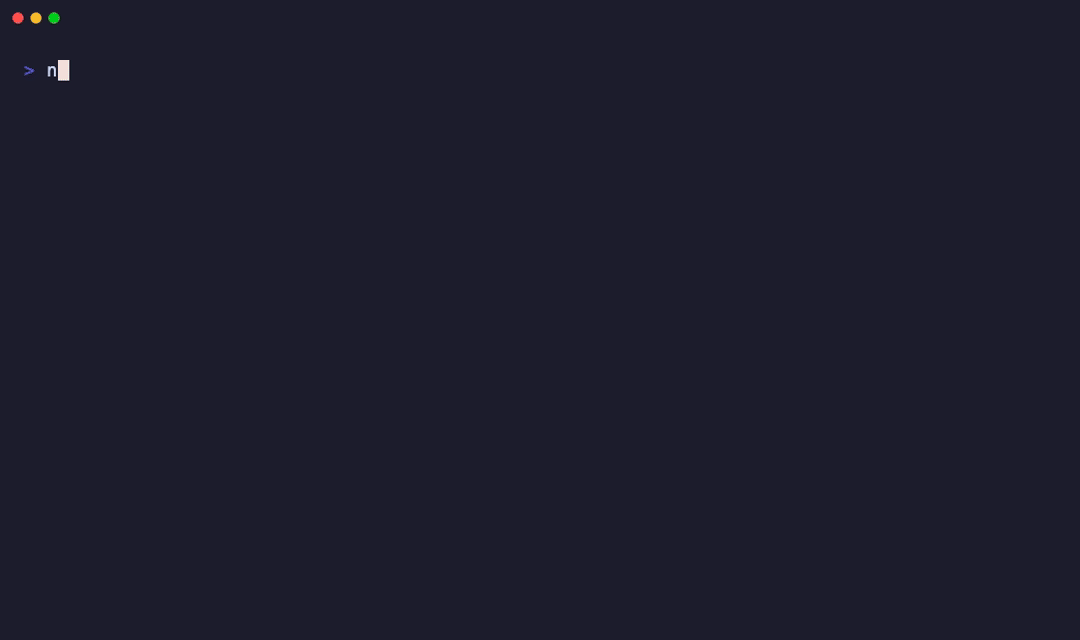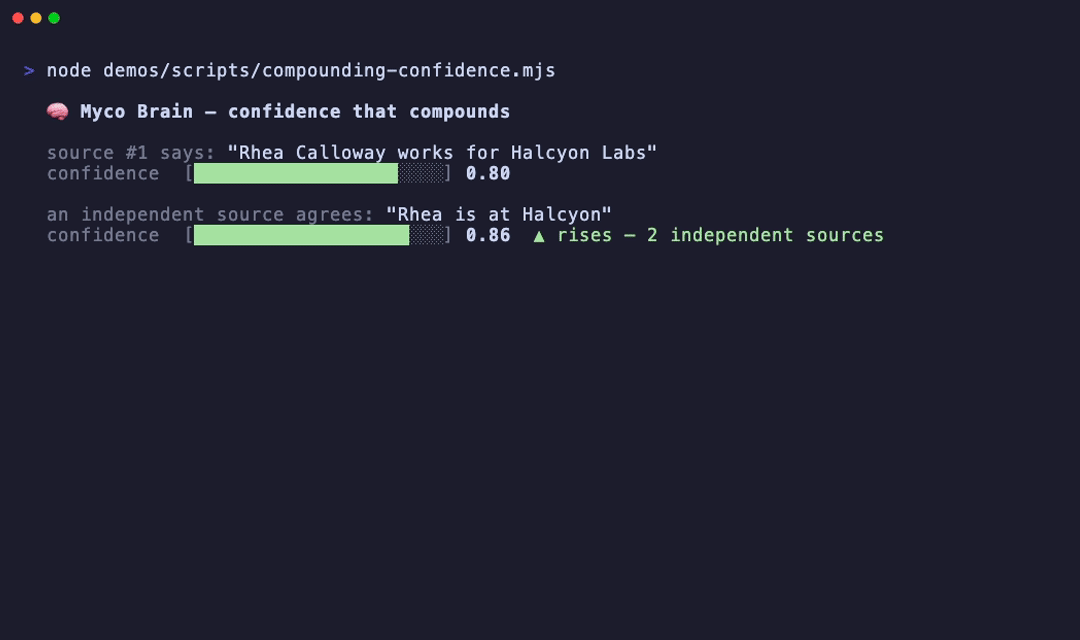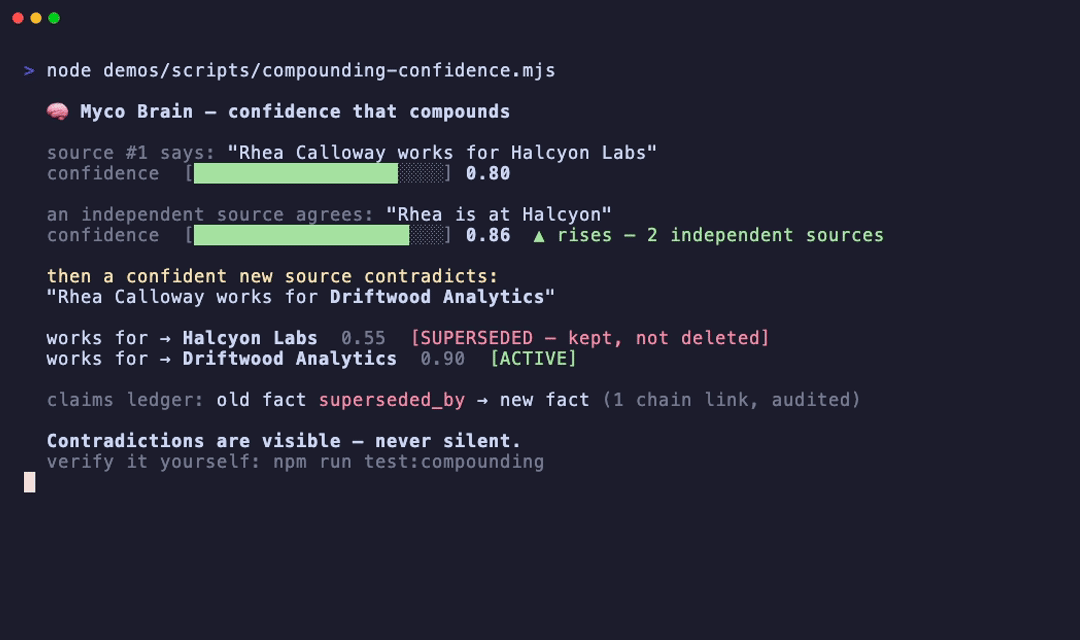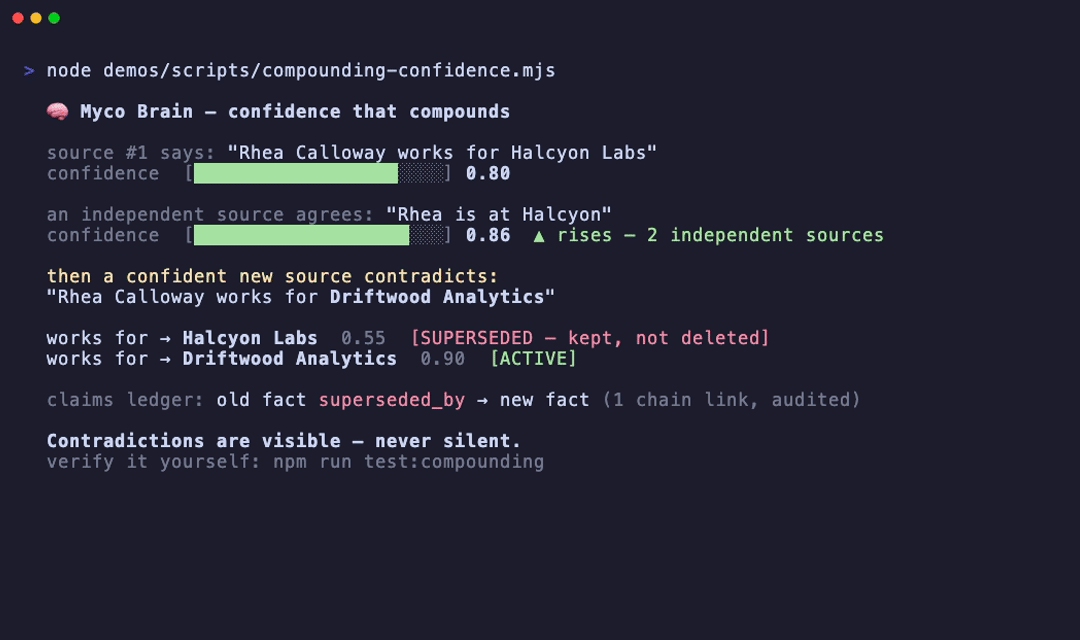
Most agent memory overwrites facts silently. Myco Brain compounds them:
- An independent source agreeing with a fact raises its confidence
(damped noisy-OR — ten chunks of one document corroborate nothing; only
distinct sources count).
- A confident contradiction on a single-valued relationship (who you work
for, where something is located) supersedes the old fact: it's
closed and weakened — kept, never deleted — with the supersession
recorded in an audited claims ledger.
- Ask brain_why about any fact and you get its distinct source count (per
relationship, not per mention), its confidence trend over time ("0.8 → 0.86"),
and any superseded history.
Contradictions stay visible. Your memory can't gaslight you.
works for → Halcyon Labs           0.55  [SUPERSEDED — kept, not deleted]
works for → Driftwood Analytics    0.90  [ACTIVE]
claims ledger: old fact superseded_by → new fact (audited)
Proof: npm run test:compounding — the full lifecycle runs against a live
database in seconds, no LLM required.
The schema evolves with your data (dynamic schema)
- The extraction worker notices entity kinds and relationship types your catalog
doesn't have yet and proposes them (brain_stats: "Brain proposed 3 new
types from your data").
- Promotion is yours by default — or opt into auto-promotion for types
corroborated across enough distinct source documents
(BRAIN_SCHEMA_AUTO_PROMOTE=1), counted per document, not per mention, so two
documents passed back and forth can't manufacture consensus. One chatty
document can never promote anything.
- A promoted type stays scoped to the workspace that earned it — one client's
vocabulary never leaks into another's catalog (see
per-client isolation).
Proofs: npm run test:dynamic-schema, npm run test:schema-promotion.
You pick the trust dial:
| Mode | Behavior |
|---|---|
| Default | Confident facts auto-promote; novel types wait for review |
| BRAIN_REQUIRE_HUMAN_REVIEW=1 | Strict curation — nothing the LLM proposes touches the canonical graph without a human decision |
| BRAIN_SCHEMA_AUTO_PROMOTE=1 | Corroborated new types promote themselves, audited |
When something is waiting on you — novel types in default mode, or everything
in strict mode — review it from the command line:
mycobrain review                 # list pending entities, relationships, types
mycobrain review approve <id>    # promote it into the graph
mycobrain review reject  <id>    # reject it (kept and audited, never deleted)
Proof: npm run test:review — approving actually lands the entity / edge /
type in the canonical graph; rejecting never does.
Private memories, shared knowledge
Multi-agent teams get real isolation: documents marked private are readable
only by the agent that created them — enforced in every read tool, on top
of workspace row-level security. Workspace memory stays shared. Proof:
npm run test:sharing (a two-agent visibility matrix). Like workspace
isolation, it binds only under the least-privilege brain_app role
(security note).
One isolated workspace per client — built for agencies
…
Sign in to leave a review
Use Google, GitHub, or an email account so ratings stay tied to real people.
No reviews posted yet.