PDF Reader MCP Server (@sylphlab/pdf-reader-mcp)
About
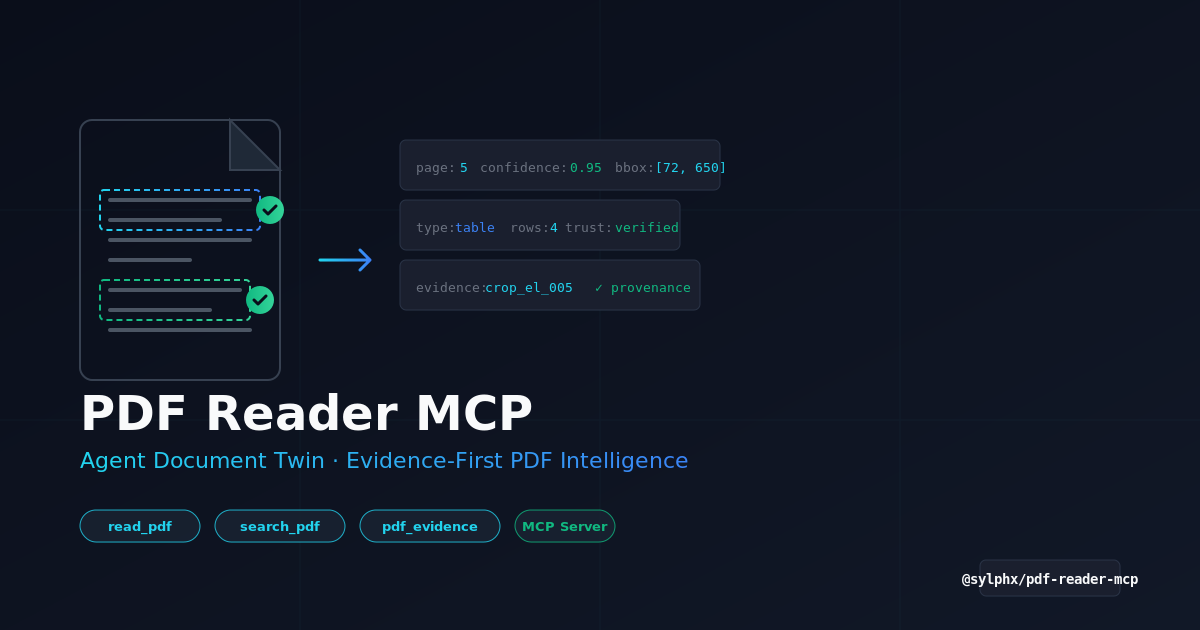
📄 The PDF intelligence layer for AI agents — Agent Document Twin, evidence-first extraction, visual crops, OCR provenance, trust reports, and benchmark-gated releases. MCP server for Claude, Cursor, VS Code, and any MCP client.
Details
- License
- MIT
Explore
- Agent Document Twin with lossless, visual, semantic, evidence, and agent layers.
- One smart read_pdf tool that auto-profiles and extracts with evidence.
- OCR adapter for scanned pages via configured providers (e.g. Tesseract).
- Visual crops, region analysis, and provider‑normalized evidence.
- Trust reports for hidden text, unsafe links, spoofing, and prompt injection.
- Accessibility reports for tagged‑PDF coverage, headings, links, and forms.
- Deterministic quality benchmarks and release gates for shipped proof.

Setting up with Highlight
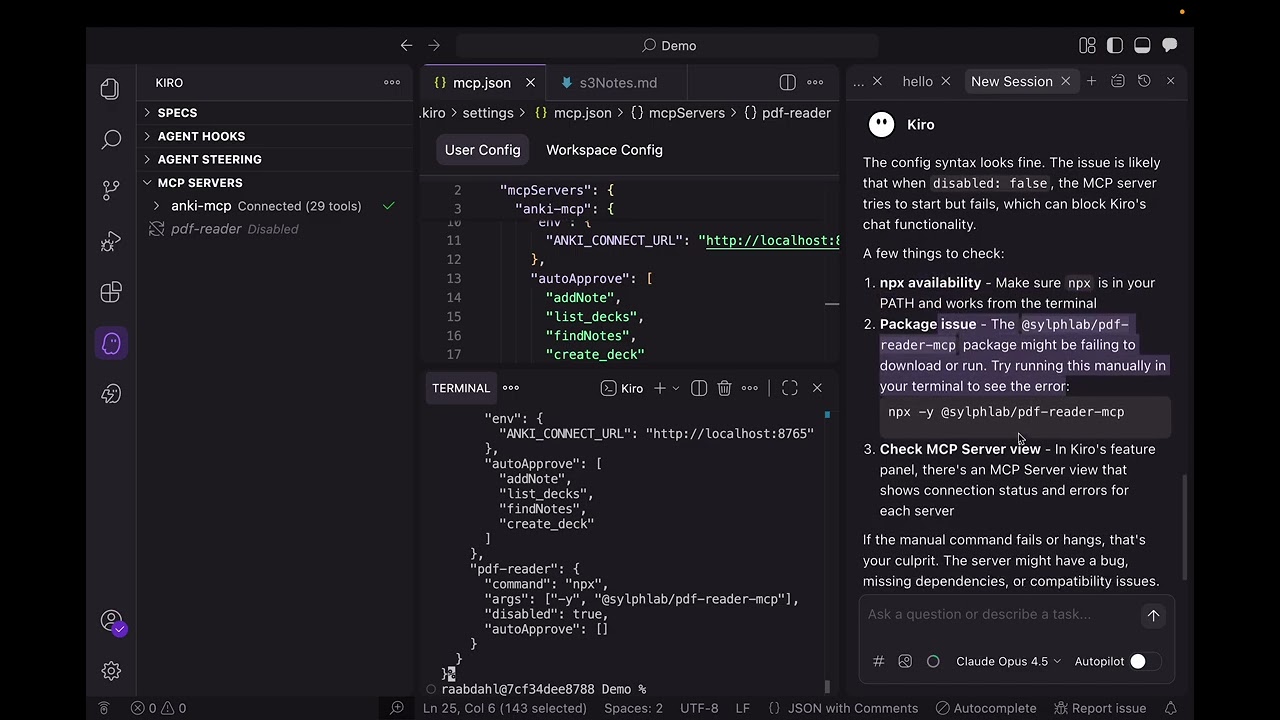
This MCP is not yet compatible with Highlight’s one-click setup. However, you can still use it with Highlight by following these steps:
- Download and install Highlight from highlightai.com/download
- Navigate to the plugins tab and select "Add Custom Plugin"
-
Configure the plugin with the settings below
Plugin Name
PDF Reader MCP Server (@sylphlab/pdf-reader-mcp)Command (node, npx, python, etc.)Please refer to the README for specific instructions on how to obtain API keys or other required environment variables.
- Enable "Start Automatically" if you want the plugin to start when Highlight launches





From the repository
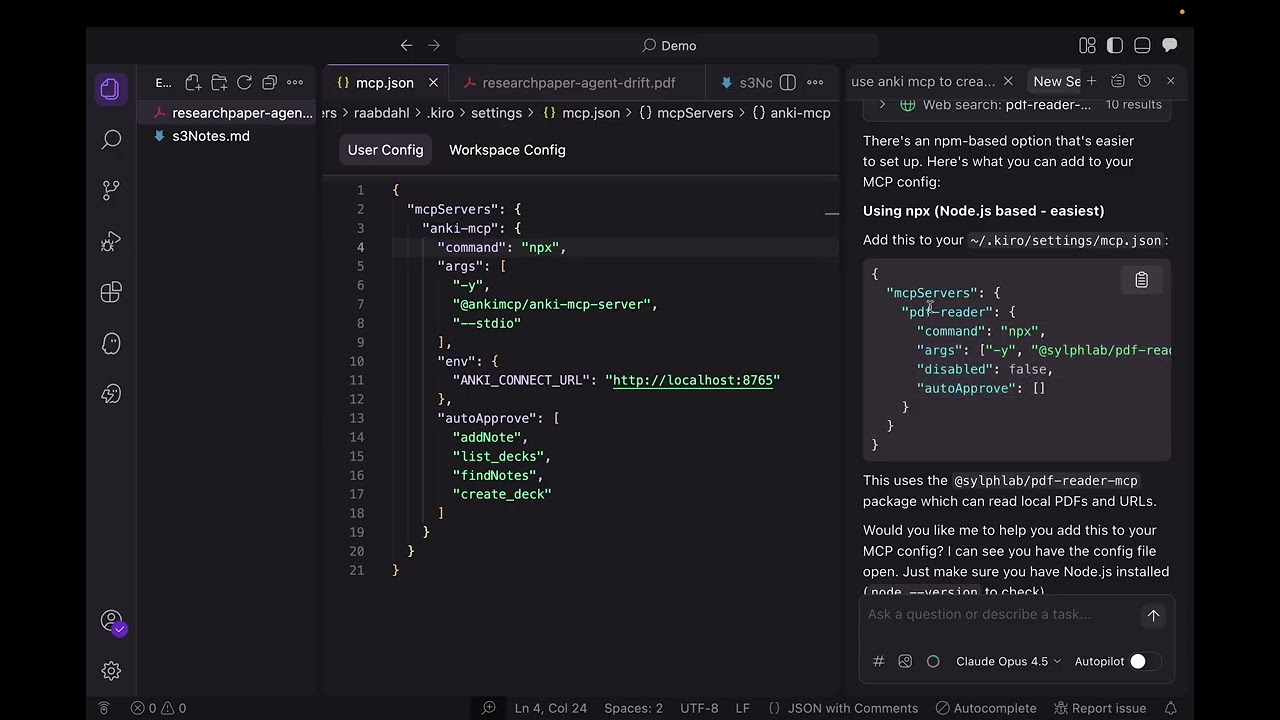
Install the npm package @sylphx/pdf-reader-mcp (Node.js ≥22.13 required) via npx, or use the Docker image from GitHub Container Registry. Add it to Claude Desktop config, Claude Code, or any MCP client. The default package works without OCR models, vision models, or cloud credentials. Use the read_pdf tool first with only sources to auto-profile and read the PDF, or use explicit include_* options for precise control. Also supports search_pdf and pdf_evidence tools.
read_pdf
Use first. With only `sources`, it auto-inspects and reads the PDF in one call; with explicit `include_*` options, it runs precise manual extraction.
search_pdf
Search selectable text and optional OCR text with snippets, offsets, boxes, and provenance.
pdf_evidence
One focused evidence tool for `inspect`, `render_page`, `extract_regions`, `ocr_pages`, and `analyze_regions` operations.
The default V3 agent path is one tool call:
{
"sources": [{ "path": "/absolute/path/to/report.pdf" }]
}
With no manual include_ flags, read_pdf profiles each PDF, chooses the
extraction route, and returns the Agent Document Twin in one response. Digital
text PDFs get Markdown, chunks, tables, layout routing, and source evidence.
Mixed or scanned PDFs are routed toward configured OCR and visual providers
when those providers are ready. Metadata, page geometry, warnings, provider
readiness, and the selected read_pdf arguments are included so the agent can
see what happened.
Agents can still force auto: false and use explicit include_ options for a
precise manual extraction. Use auto_detail: "fast", "balanced", or
"full" when the agent wants to control output depth without learning dozens
of switches.
| Tool | Use it when the agent needs to... |
| --- | --- |
| read_pdf | Use first. With only sources, it auto-inspects and reads the PDF in one call; with explicit include_* options, it runs precise manual extraction. |
| search_pdf | Search selectable text and optional OCR text with snippets, offsets, boxes, and provenance. |
| pdf_evidence | One focused evidence tool for inspect, render_page, extract_regions, ocr_pages, and analyze_regions operations. |
Full request and response details live in the API reference.
Claude Desktop / Cursor
Paste into your MCP client config file to install this server.
{
    "mcpServers": {
        "pdf reader mcp server (@sylphlab/pdf-reader-mcp)": {
            "pdf-reader-mcp-sylphlab": {
                "command": "npx",
                "args": [
                    "@sylphx/pdf-reader-mcp"
                ]
            }
        }
    }
}McpServers
{
    "pdf-reader-mcp-sylphlab": {
        "command": "npx",
        "args": [
            "@sylphx/pdf-reader-mcp"
        ]
    }
}
📄 @sylphx/pdf-reader-mcp
> The PDF intelligence layer for AI agents that need source evidence, not just extracted text.


V3 smart tool surface · Agent Document Twin · Evidence-first extraction · Visual crops · OCR adapters · Tables, charts, formulas, figures · Trust & accessibility reports · Benchmark-gated releases
<a href="https://mseep.ai/app/SylphxAI-pdf-reader-mcp">

</a>
</div>
---
PDFs are not plain text files. They are layout, pixels, tables, hidden text,
permissions, annotations, scanned pages, and ambiguous reading order.
PDF Reader MCP turns that mess into an Agent Document Twin: a linked,
source-backed representation of the PDF that agents can inspect, search,
verify, crop, OCR, enrich, cite, and read with confidence.
If your agent has ever hallucinated from a PDF, lost a table, trusted hidden
text, missed a scanned page, or needed to cite the exact region that proves an
answer, this is the MCP server for that workflow.
Why Agents Use It
| Need | What PDF Reader MCP gives you |
| --- | --- |
| Read the document | Markdown, JSON, HTML, page text, metadata, chunks, and semantic AST. |
| Prove the answer | Page numbers, bounding boxes, evidence IDs, region crops, and source renders. |
| Handle scanned PDFs | Rendered pages routed through configured OCR providers with word boxes and provenance. |
| Recover tables | Selectable-text and OCR-derived tables with cells, geometry, confidence, warnings, and continuation hints. |
| See what text extraction misses | Visual page evidence, focused crops, and configured visual-region provider adapters. |
| Protect the agent | Trust reports for hidden text, prompt-injection-like content, visual spoofing, unsafe links, and redaction. |
| Route accessibility work | Tagged-PDF coverage, tag-visible coverage, headings, images, forms, links, permissions, and page grades. |
| Ship with proof | CI, package smoke, deterministic quality benchmarks, provider artifacts, and release gates. |
Quick Start
Claude Code
claude mcp add pdf-reader -- npx @sylphx/pdf-reader-mcp
Claude Desktop
Add this to claude_desktop_config.json:
{
  "mcpServers": {
    "pdf-reader": {
      "command": "npx",
      "args": ["@sylphx/pdf-reader-mcp"]
    }
  }
}
Any MCP Client
npx @sylphx/pdf-reader-mcp
Node.js >=22.13 is required. The default package works without downloading
OCR models, vision models, Ollama, LM Studio, llama.cpp, or cloud credentials.
Docker
```bash
Sign in to leave a review
Use Google, GitHub, or an email account so ratings stay tied to real people.
No reviews posted yet.